Know which QA criteria actually move your business metrics
Birdie scores 100% of your calls, chats, emails and bot conversations against the rubric you already use. Then it shows which criteria move repeat contacts, CSAT and churn, and helps you improve them.
Book a demo


“We can now quickly quantify business impact and correlate feedback with customer segments and behavior.”
Name


Your scores look fine. Your numbers don't.
Most teams review 2 to 5% of interactions against a rubric set by committee and never tested against an outcome. That is how a green dashboard and a rising repeat contact rate coexist in the same quarter.

Limited and fragmented evaluations - even with AI
Most QA still relies on samples, not the full picture. Even AI may score interactions in isolation, missing broader patterns.

Slow, reactive detection
Issues are found after they spread. By the time they appear in reports, friction, repeat contacts, and costs are already rising throughout the operation.

No connection to business outcomes
Traditional QA measures compliance, but rarely shows how behaviors affect CSAT, retention, resolution, or efficiency.

Hard to scale meaningful insight across interactions
Manual reviews cover only a small share of conversations. That limits visibility across teams, channels, and vendors.
Evaluate everything. Find what matters. Prove the fix.
One loop, not a dashboard. The QA you already run becomes a decision you can defend to finance.
Every interaction, not a sample
Full coverage on the rubric you already use.
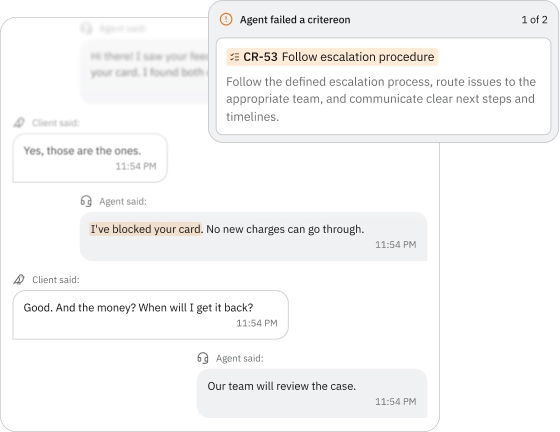

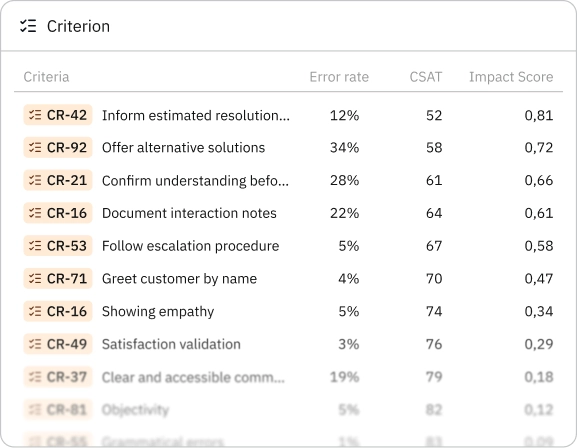
Which criteria earn their weight
Each criterion is tested against the outcome it claims to drive. Each issue is traced to whoever owns it.
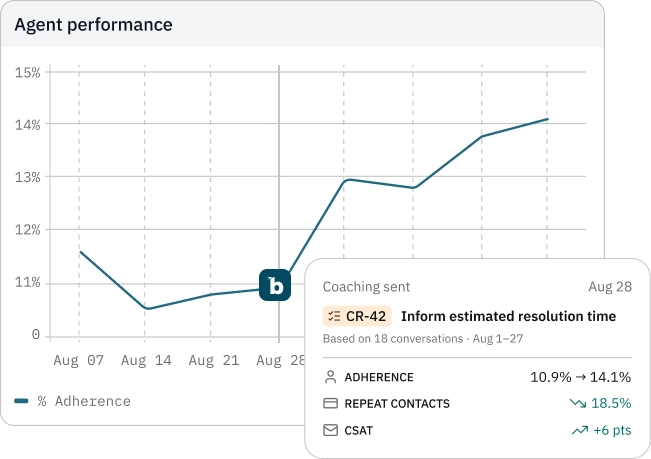
The metric moves, or it didn't work
Coaching, training or a process fix, routed with the conversations attached. Then measured against the number you report on.
What teams use it for

Catch disclosure gaps before the examiner does
Every interaction checked for required language and risk patterns, not a 3% sample.

Find the handling that makes customers stay
Behaviors correlated to loyalty, so coaching goes where it changes something.

Separate bad handling from bad product
Contacts your team mishandled, split from contacts your product created.

Grade your bots on the same rubric as your people
Independent scoring, so the AI vendor is not marking its own work.
How Birdie compares with manual QA and AutoQA tools.
Manual QA tells you who scored low. AutoQA tells you the same thing faster. Neither tells you whether the scorecard was ever right.
Birdie Frontline Intelligence
✓
100% scored, human and AI agents
✓
Near real time, with the fix attached
✓
Which behaviors move your metric
✓
Tested against customer outcomes
✓
Traced to product or process, with an owner
✓
Independent, same rubric as your people
✓
Movement in CSAT, retention and cost
Coverage
Speed
What it answers
The rubric
When the agent isn't the problem
AI agent quality
Proof of impact
Manual QA
2% to 5% sample
One to two weeks
How did this score
Defended by committee
Invisible
Not covered
Score trend
AutoQA tools
100% scored
Near real time
Which agents score low
Automated as written
Invisible
Often the vendor grading itself
Score trend
Birdie Frontline Intelligence
✓
100% scored, human and AI agents
✓
Near real time, with the fix attached
✓
Which behaviors move your metric
✓
Tested against customer outcomes
✓
Traced to product or process, with an owner
✓
Independent, same rubric as your people
✓
Movement in CSAT, retention and cost
KOHO found a quarter of its support volume hiding under one label.
Inside a category called "login issues" were five or six distinct failure points, each with a different cause and a different fix. A label like that can be reported on. It cannot be handed to an engineer.
“The best experience is when someone doesn’t actually have to reach support. So we do a lot with our product team to make sure that we are driving down as many conversations as possible. Birdie’s really enabled this in an amazing way.”
Monika Aufdermauer
of support volume traced to one root cause
lower inbound contact volume
CSAT after the fixes shipped
Where Frontline Intelligence sits
Customer Intelligence covers what customers are experiencing. Frontline Intelligence covers how your company responds, human or AI. Together, they drive continuous improvement, from signal to action to proof.
Inputs

Birdie Platform

Outcomes

NPS surveys
Transactional & relational

Customer reviews
App stores, G2, public

Support tickets (Call + Chat)
Zendesk, Intercom, Salesforce

Social mentions
X, Reddit, LinkedIn, forums
MCP
Customer Intelligence
What they experience
Frontline Intelligence
How you respond
Birdie
Customer Context Platform
Frontline Intelligence
How you respond
Customer Intelligence
What they experience
MCP
CSAT lift and NPS gains
Move the satisfaction needle
Reduce churn
Fewer touches per case
Coaching at scale
QA on 100% of conversations
Effective customer support
First contact resolution
Inputs
NPS surveys
Transactional & relational
Customer reviews
App stores, G2, public
Support tickets (Call + Chat)
Zendesk, Intercom, Salesforce

Voice calls
Recorded & transcribed

Chat conversations
Live chat & messaging
Social mentions
X, Reddit, LinkedIn, forums
Birdie Platform
Customer Context Platform
Frontline Intelligence
How you respond
Customer Intelligence
What they experience
MCP


Outcomes
CSAT lift and NPS gains
Move the satisfaction needle
Reduce churn
Fewer touches per case
Coaching at scale
QA on 100% of conversations
Effective customer support
First contact resolution
NPS gains
Compounding loyalty over time
Coaching at scale
QA on 100% of conversations
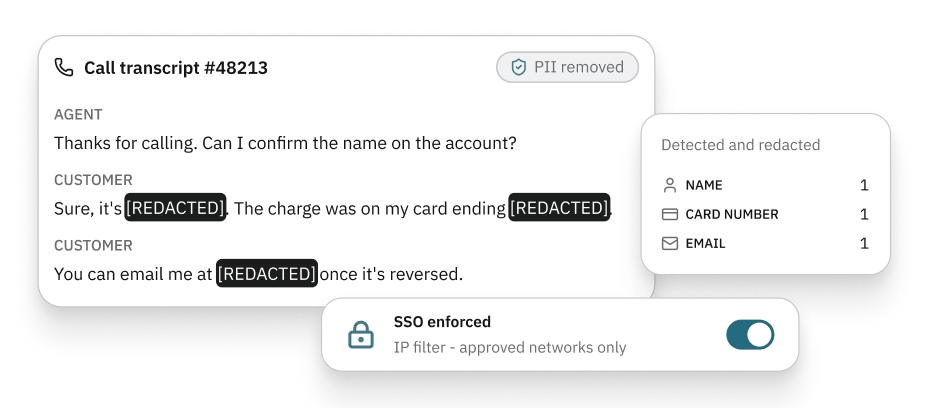
Built for regulated environments
Encrypted, access controlled and audit logged to the standards of fintech and healthcare operations.
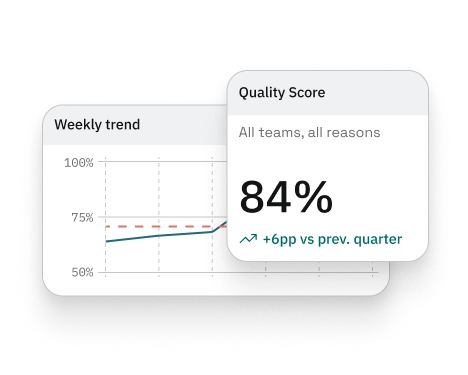
Accuracy you can inspect
We publish F1 scores and model cards, including limitations and edge cases. Every score traces back to its reasoning.
Connected to where work happens
Signals in from Zendesk, Slack, surveys and reviews. Decisions out to Jira, Asana and your AI agents, with full context.
How is this different from AutoQA and AQM tools?

AutoQA uses AI to score interactions instead of a person. AQM adds coaching, calibration and performance tracking around it. Birdie is an AQM solution with the layer most tools skip: because Frontline Intelligence sits alongside Customer Intelligence on one platform, quality signals are read against CSAT, retention, first contact resolution and cost.
Can it evaluate AI agents and chatbots?
Yes. Bot and virtual agent conversations are scored on the same rubric as your human teams, so containment and quality are comparable, and AI agents are checked for the same compliance risk as people. This matters most when the AI agent's vendor also supplies its quality scoring. Independent evaluation avoids the vendor marking its own work.
Does this replace my QA team?
No. It replaces the listening and scoring that consumes most of their week. Analysts move to calibration, edge cases and coaching, with patterns from every conversation instead of a handful of calls.
Most teams phase the rollout, starting with one team or channel.
How do you handle calibration and disputed scores?
Birdie's models learn your terminology, edge cases and scoring philosophy over time, and you can flag disagreements to refine accuracy. QA leads can also score an interaction manually and compare against the AI score. Discrepancies show where the rubric needs clarifying or the model needs adjusting. When an agent disputes a score, you have the evidence and the reasoning, not a judgment call.
Should we build this ourselves?
The model call is the easy part. Ownership is the part that never ends: policies change, teams change, scoring definitions drift. A drifted evaluator doesn't fail loudly. It keeps answering confidently with something that stopped being true, and you find out months later through a wrong coaching decision or a missed compliance flag. Compare year three cost of ownership, not the version one build cost.
What does it take to get started?
Birdie connects to the systems where your interactions already live, so the lift is integration, not migration. Timeline depends on how many channels you connect and how your data is structured.
Bring us 100 of your interactions.
We score them against your rubric and show which criteria correlate with the metric you are held to. 30 minutes, live.